Klara Wolf · 28 September 2026
Navigating Synchronization Hurdles in Distributed Productivity Ecosystems During Platform Upgrades
Distributed productivity ecosystems rely on continuous data exchange across multiple nodes, and platform upgrades introduce temporary disruptions that affect synchronization protocols. Researchers have documented how these systems must maintain consistency while handling version transitions, latency spikes, and concurrent user sessions that span different geographic regions.
Studies from the National Institute of Standards and Technology show that upgrade windows often coincide with increased error rates in distributed databases, where changes to schema definitions propagate unevenly across replicas. Data indicates that organizations running collaborative tools experience measurable drops in throughput when synchronization queues back up during these periods.
Core Synchronization Challenges in Distributed Setups
Version conflicts emerge when individual components receive updates at staggered intervals, leaving some nodes operating on older schemas while others process new data formats. Observers note that this mismatch forces rollback mechanisms into action, yet those mechanisms can themselves create secondary inconsistencies if not coordinated across the entire cluster.
Network partitions during upgrades further complicate matters because nodes separated from the primary control plane continue to accept local changes that later require reconciliation. Evidence from academic analyses reveals that reconciliation algorithms must handle both the volume of pending operations and the ordering constraints imposed by causality tracking.
Observed Patterns During Major Upgrade Cycles
Platform teams that schedule upgrades in September 2026 encountered heightened synchronization demands as multiple vendors released coordinated releases within the same two-week window. Figures from industry monitoring services indicate that cross-platform dependencies amplified the effect, with delays in one service creating ripple effects that lasted several days beyond the initial maintenance window.
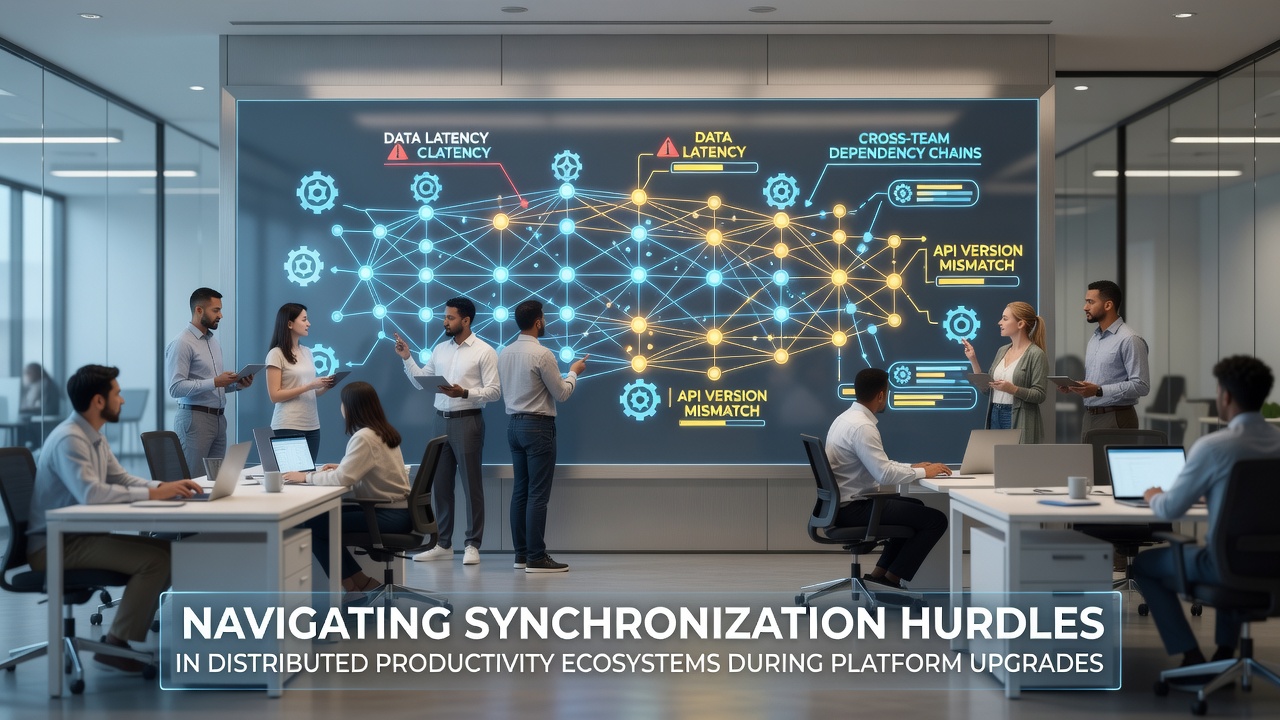
Those who studied these events found that pre-upgrade simulation testing reduced the duration of lag spikes, although it did not eliminate them entirely. The reality is that live traffic patterns often deviate from test scenarios, particularly when user behavior shifts in response to announced maintenance.
Approaches That Address Coordination Gaps
Incremental rollout strategies allow subsets of nodes to receive updates while maintaining read replicas that serve consistent views to connected clients. Research indicates that combining these rollouts with feature flags enables rapid reversal if synchronization errors exceed defined thresholds.
Consensus protocols such as Raft and Paxos receive adjustments during upgrade planning so that leader election processes account for nodes that may temporarily operate in maintenance mode. Experts have observed that tuning election timeouts and heartbeat intervals helps stabilize clusters when network conditions fluctuate.
Logging and audit trails become critical because post-upgrade analysis depends on reconstructing the exact sequence of state changes across all participants. Data from distributed tracing systems shows that correlation of timestamps across time zones requires careful normalization to avoid false positives in conflict detection.
Case Examples from Productivity Platforms
One deployment involving a multinational document collaboration service demonstrated that splitting the upgrade across availability zones limited the blast radius of synchronization failures. The team responsible for the rollout reported that monitoring tools surfaced queue-depth anomalies within minutes, allowing targeted intervention before widespread user impact occurred.
Another instance involved a task-management platform that integrated third-party calendar services. During its upgrade, mismatches in event serialization formats caused duplicate entries until a compatibility layer was activated. Those who reviewed the incident logs noted that the layer itself introduced additional latency that persisted until a subsequent patch aligned the formats.
Conclusion
Platform upgrades in distributed productivity environments continue to test the limits of existing synchronization mechanisms. Research shows that combining phased rollouts, refined consensus parameters, and comprehensive observability reduces both the frequency and severity of consistency issues. As more organizations adopt multi-cloud architectures, the patterns observed through 2026 provide a baseline for refining coordination techniques that keep data aligned across evolving systems.